

Optimizing Parallelism and Communication for Large-Scale Generative Deep Learning Systems
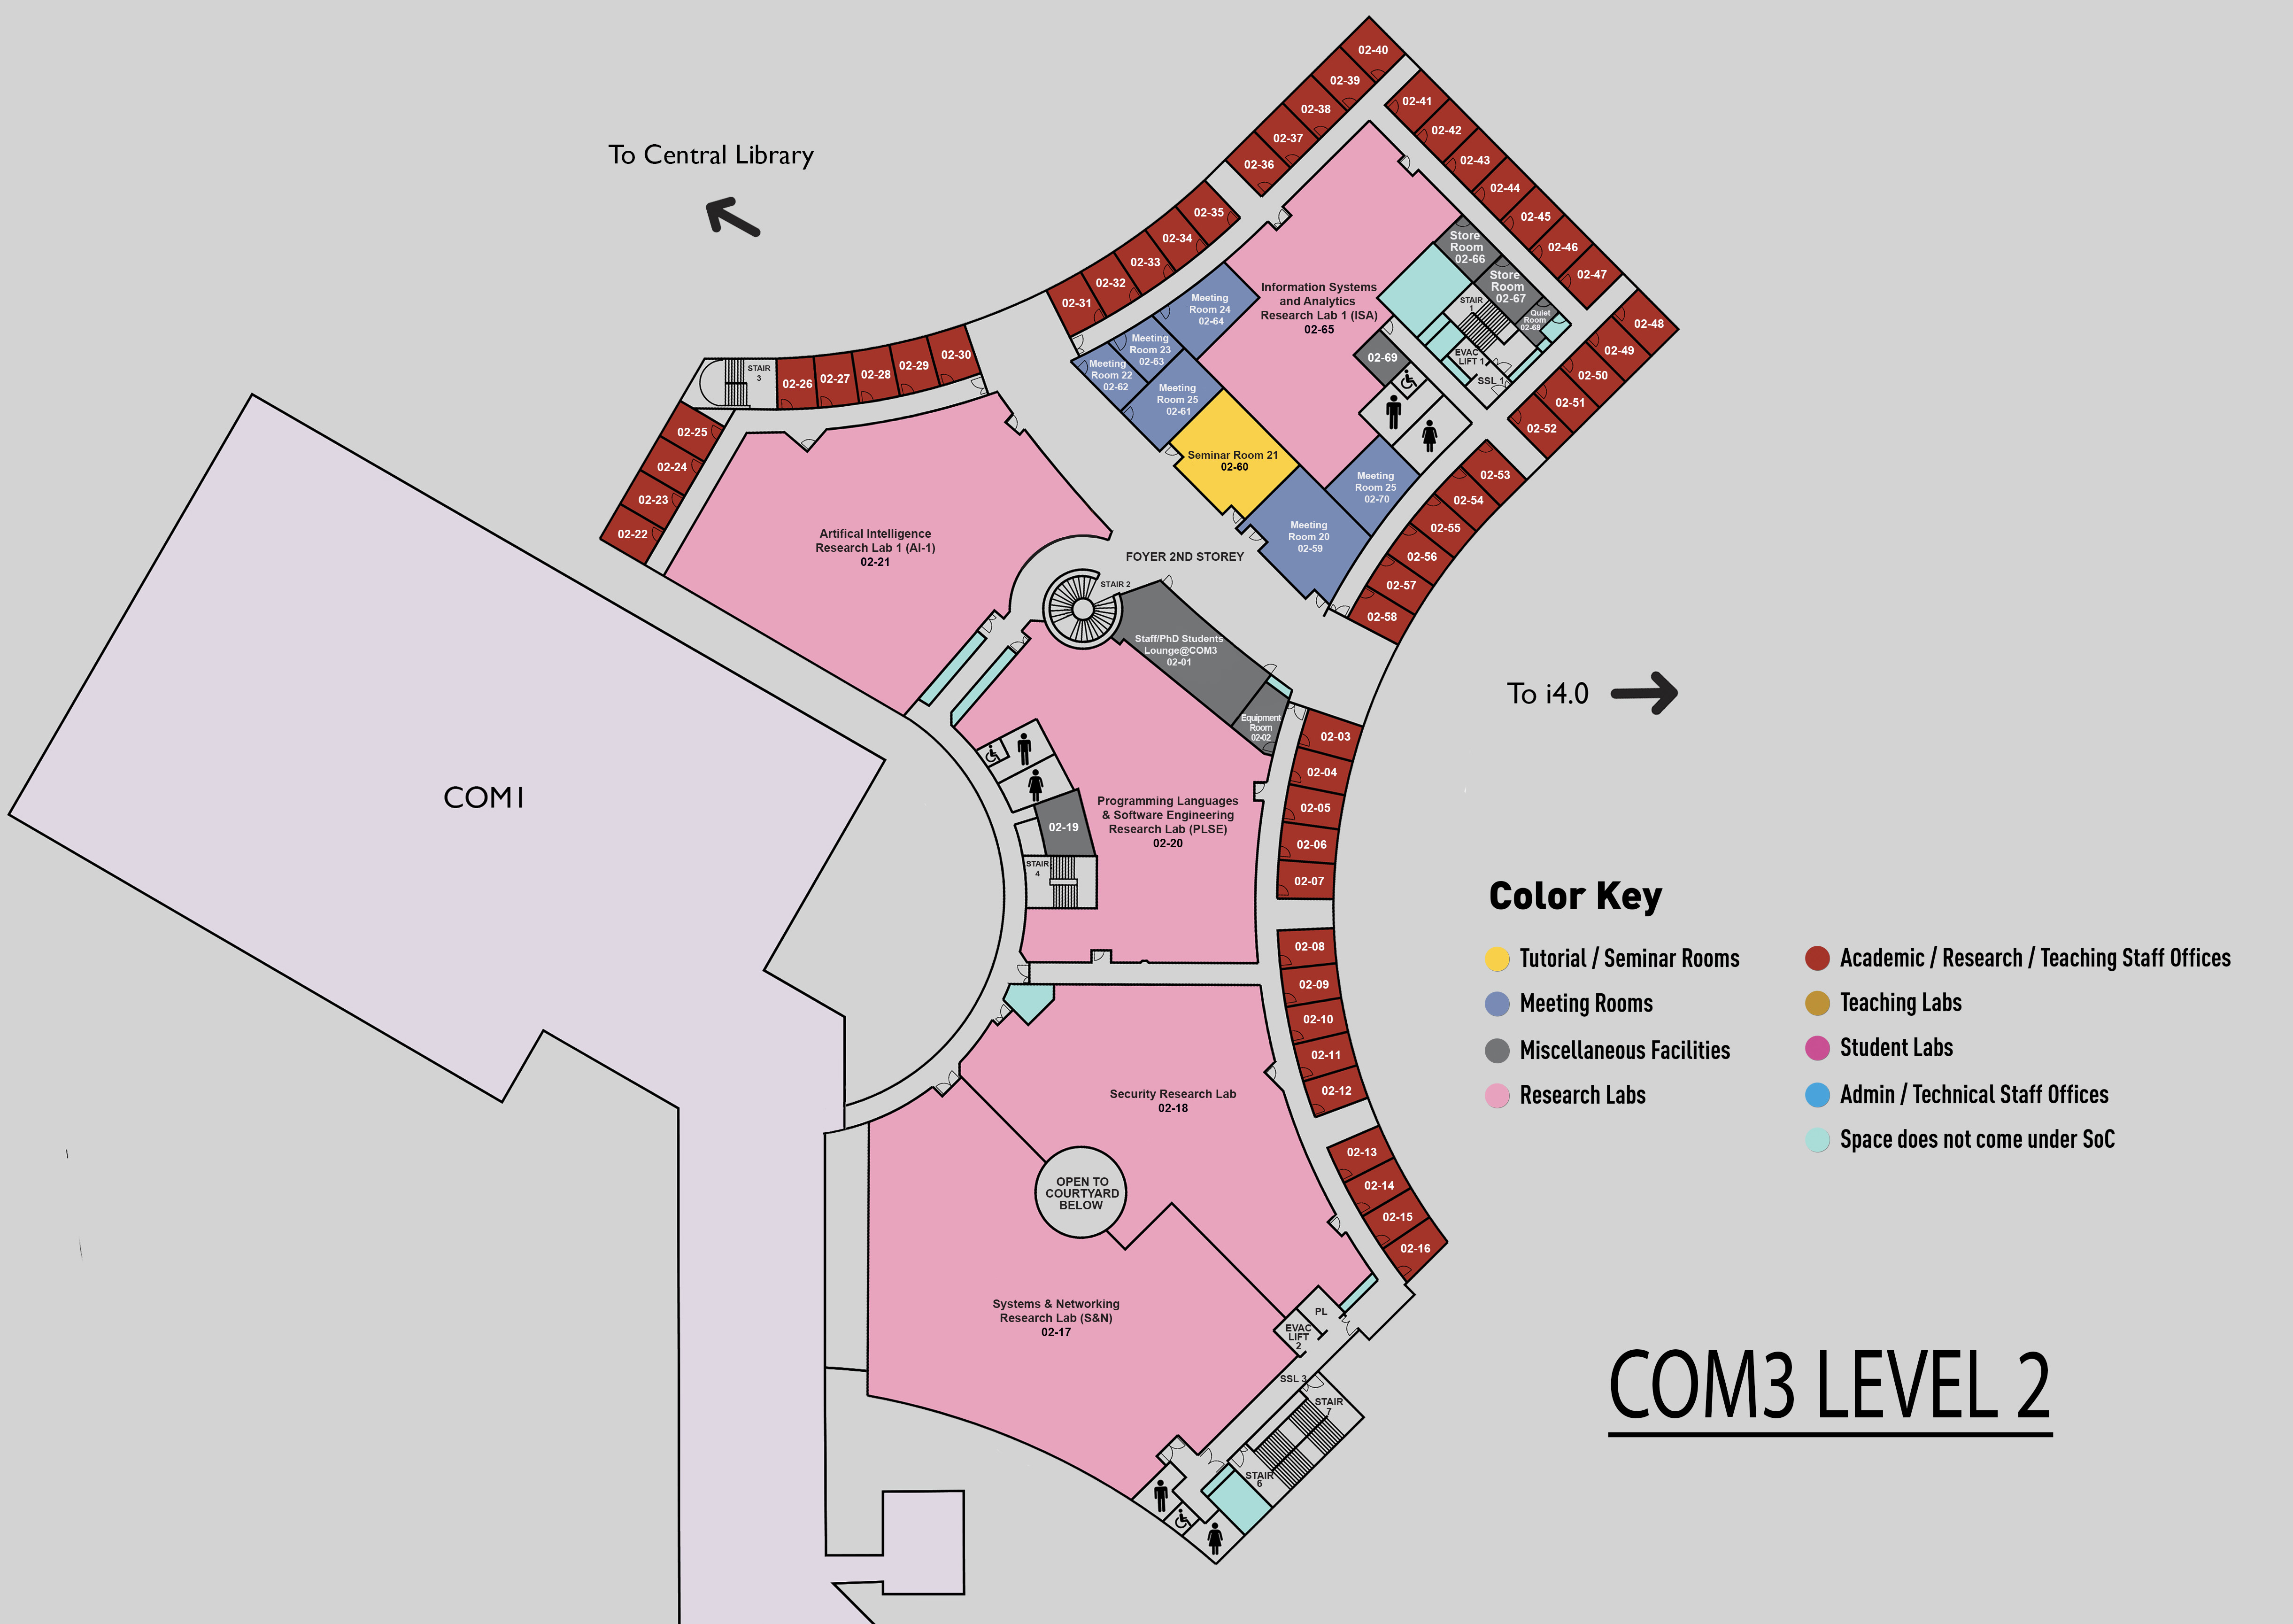
COM3 Level 2
MR24, COM3 02-64
Abstract:
Since 2014, deep learning has evolved from discriminative models to generative models. By learning data distributions, generative deep learning models are capable of generating text, images, videos, and performing reasoning. These models have enabled breakthroughs in chatbots, creative applications and scientific discovery, driving systems like ChatGPT, SORA, and AlphaFold. However, as model sizes scale from billions to hundreds of billions of parameters, training such models poses significant systems challenges, commonly referred to as the Compute Wall, Memory Wall, Communication Wall, Power Wall and Development Wall. These challenges demand highly efficient computing infrastructure, parallelization strategies, and communication optimizations.
This paper first introduces FastFold, a case study on a complex structure prediction task, demonstrating how manually designed parallel strategies and communication optimizations can significantly improve training performance. By tailoring the parallelization scheme to the model architecture and hardware characteristics, we show that communication efficiency and parallel design are critical to scaling performance.
And we propose MetaDist, which is an infrastructure framework for automatic parallelism framework with ShardCombine Algorithm. And we obviate the need for manual annotation, significantly reducing the development and maintenance cost. Moreover, our approach is natively compatible with multiple ecosystems. And then we propose Concerto, an automatic communication optimization framework for generative model training. Unlike traditional frameworks that tightly couple parallel strategies with communication logic, Concerto decouples the two and introduces an automatic decomposition and scheduling algorithm to handle both synchronous and asynchronous communication. It can automatically generate efficient communication schedules based on model structure and computation graphs, significantly reducing manual tuning effort while improving system throughput.
Finally, we present Primv, which investigates a many-core CPU architecture featuring matrix computation units and integrated on-package memory. We analyze scalability bottlenecks in CPU-based large language model training and demonstrate how a hybrid memory system can alleviate memory pressure and reduce intra-node communication overhead. Based on these insights, we propose a memory allocation strategy and integrate it into Primv, a PyTorch extension for CPU-based LLM training. Our results highlight the potential of a CPU-centric training paradigm for future AI workloads.
Through FastFold, MetaDist, Concerto, and Primv, this paper highlights the necessity of scalable systems that support complex models and diverse hardware architectures, and proposes a path toward a modular and extensible framework that incorporates parallelism and communication optimizations while automatically adapting to different architectures and hardware platforms.