

Computational and Statistical Guarantees for Algorithms on High-Dimensional Data
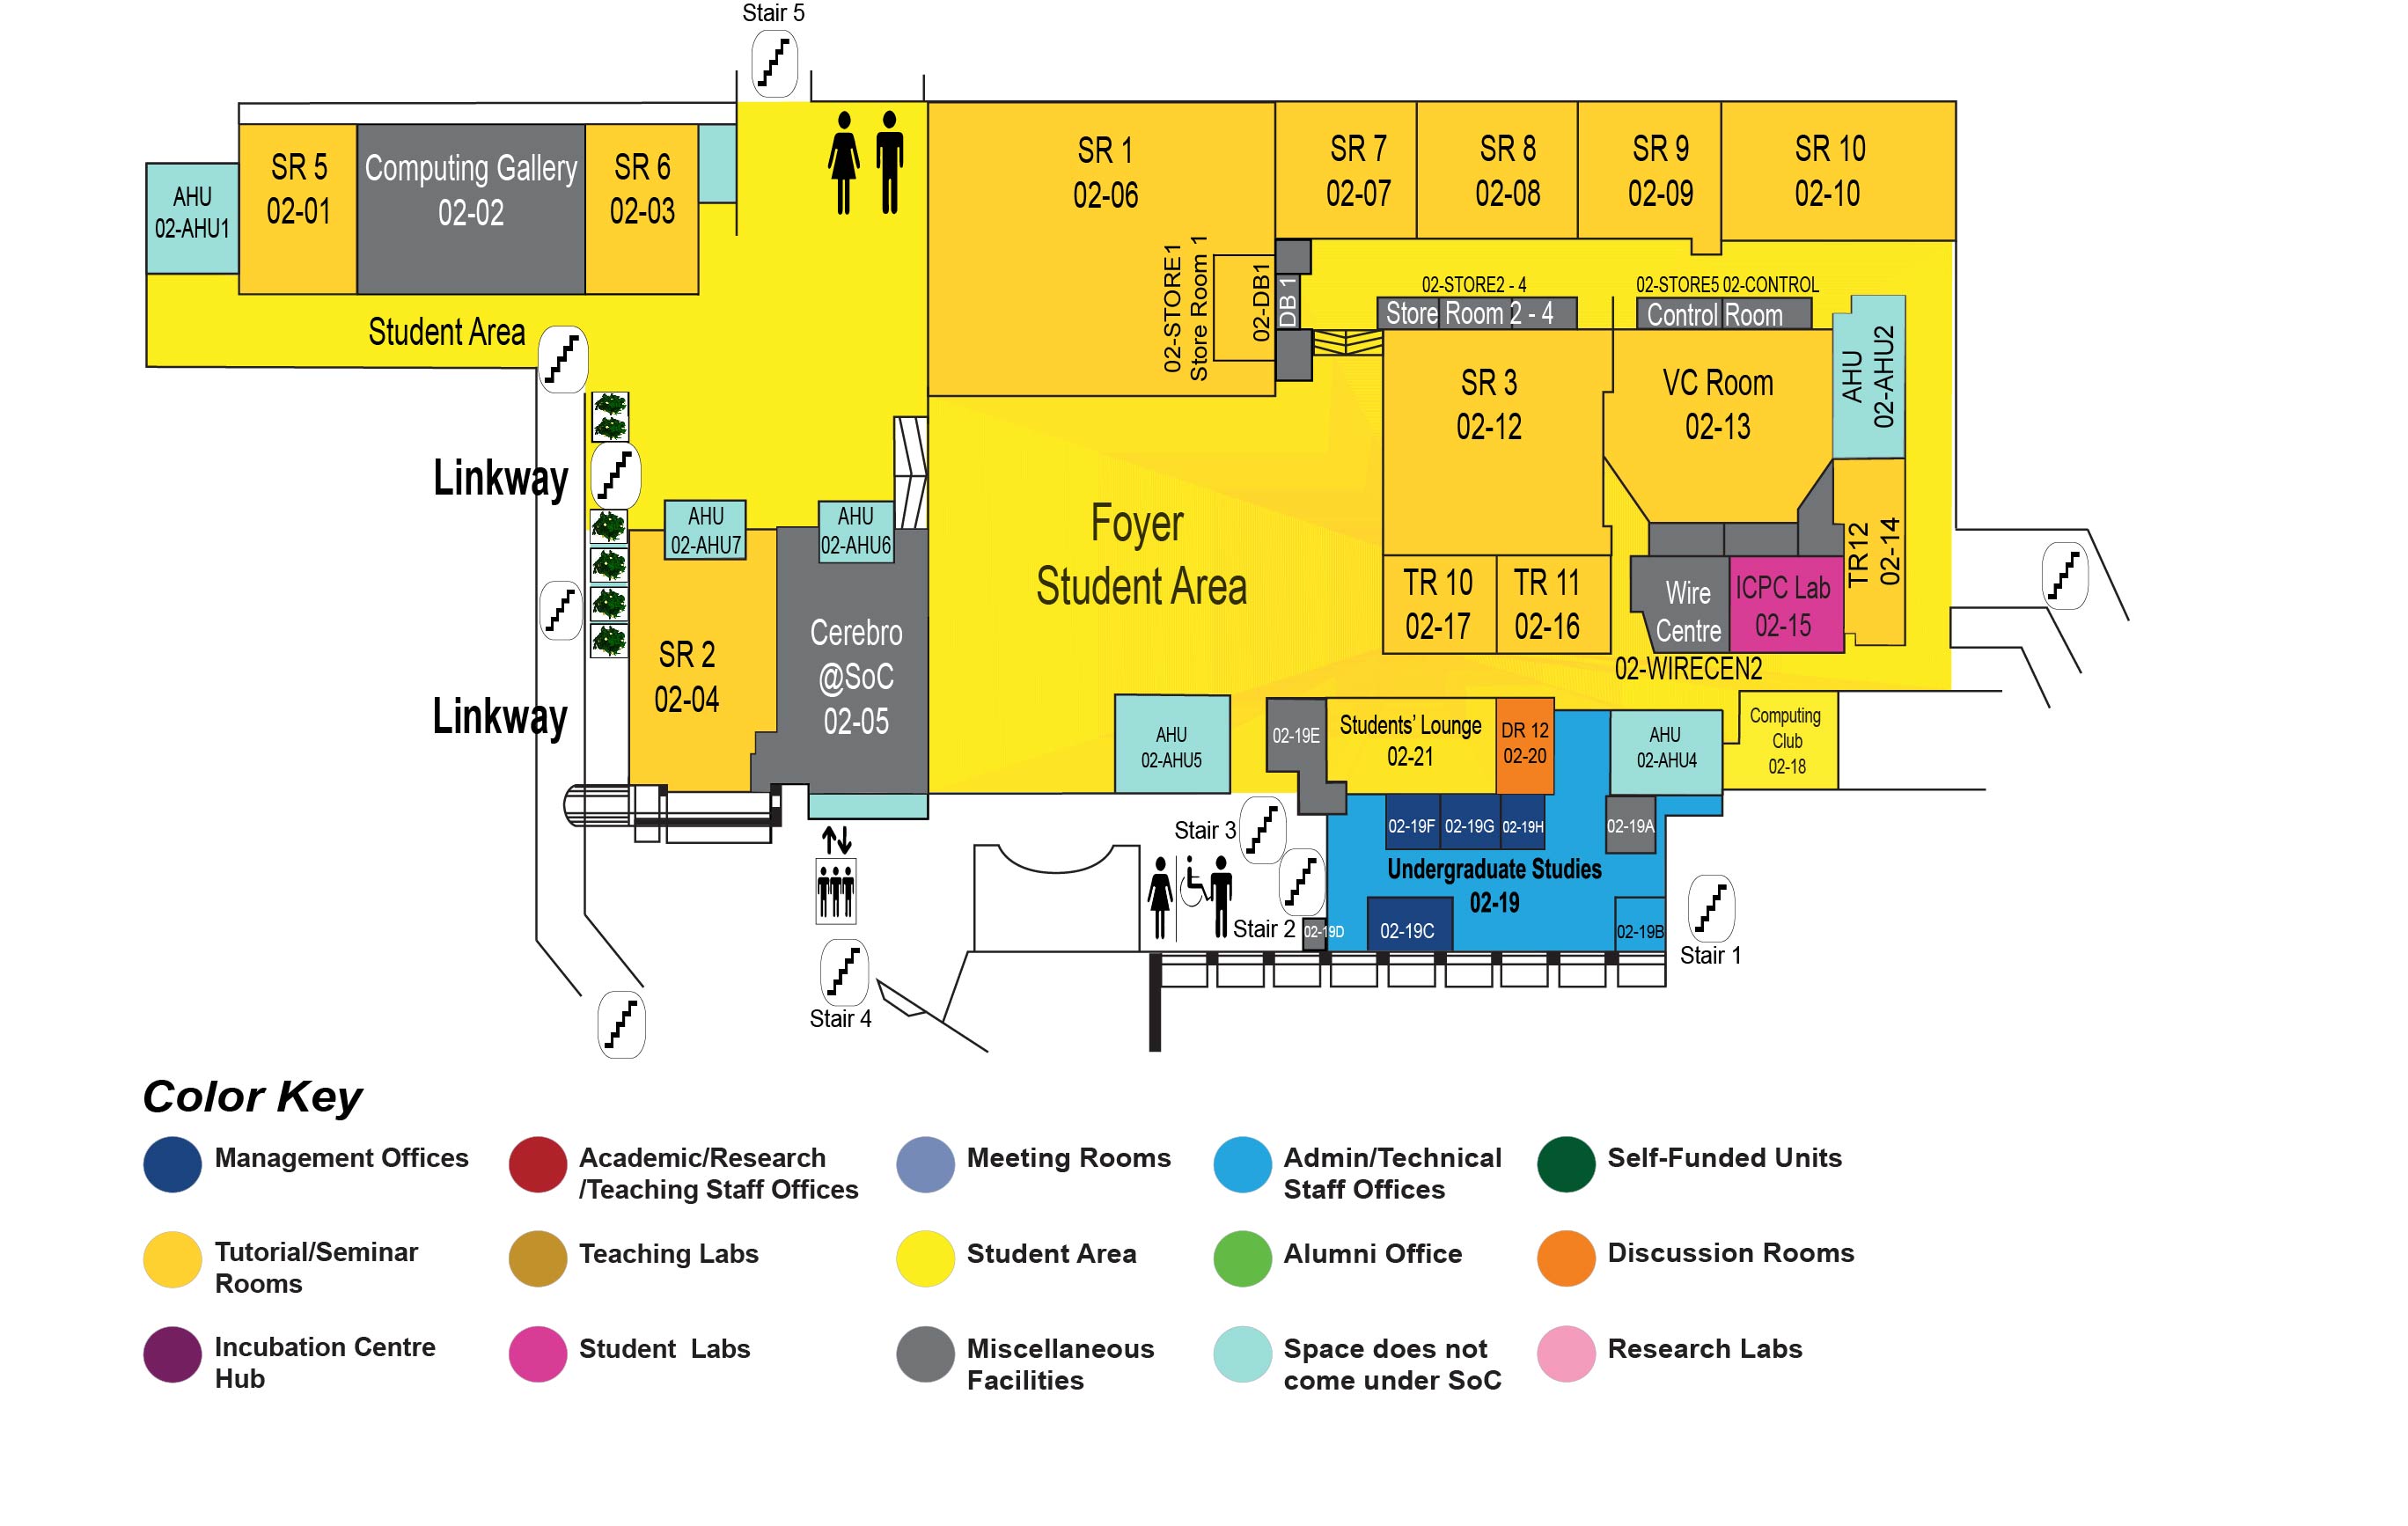
COM1 Level 2
SR2, COM1-02-04
Abstract:
The importance of computational and statistical guarantees in building reliable decision-making systems is increasingly evident in real-world applications. When working with data, we must ensure that our models are both efficient and reliable, even when the data is biased.
This thesis addresses key questions in learning, testing, and inference for high-dimensional data, introducing algorithmic innovations to handle both structured models and biased sampling.
The contributions are organized into two main themes: (I) Guarantees for unbiased data — ensuring optimal performance in applications such as financial risk assessment, and (II) Guarantees for biased data — enabling valid inference in domains such as economics and social sciences, where truncation, censoring, outliers challenge traditional methods.
In the first part, we study structured models through three main problems. Firstly, we establish general and rigorous identifiability conditions for linear Andersson–Madigan–Perlman (AMP) chain graph models, a broad class that generalizes both linear structural equation models and Gaussian graphical models, even when the chain components are unknown. Secondly, we design statistically optimal algorithms for learning Gaussian trees and polytrees, achieving the best possible rates for both distribution learning (in KL divergence) and exact structure recovery, with finite-sample guarantees and matching lower bounds. Our methods extend the Chow–Liu algorithm for trees and adapt the PC algorithm for polytrees. Finally, we develop a mutual information tester with optimal sample complexity for linear models, and apply it to structure learning via the classical Chow–Liu algorithm, achieving optimal performance guarantees in this setting.
In the second part, we investigate learning and inference from biased or incomplete data, focusing on how structural constraints, such as truncation, censoring, outliers, and unmeasured confounder bias affect fundamental statistical tasks. Firstly, we study Gaussian mean testing under truncation, where samples from a high-dimensional Gaussian distribution are only observed if they fall within a fixed subset of the domain. We then explore the learning of high-dimensional Gaussians from censored data, where certain coordinates in each sample are missing not at random. Furthermore, we establish quantitative laws governing how outliers propagate through causal mechanisms, offering new insights into model-based anomaly detection.
Collectively, these results advance the theoretical understanding of how to perform reliable inference when data are incomplete, biased, or shaped by complex causal mechanisms.