

Model Adaptation for Edge AI
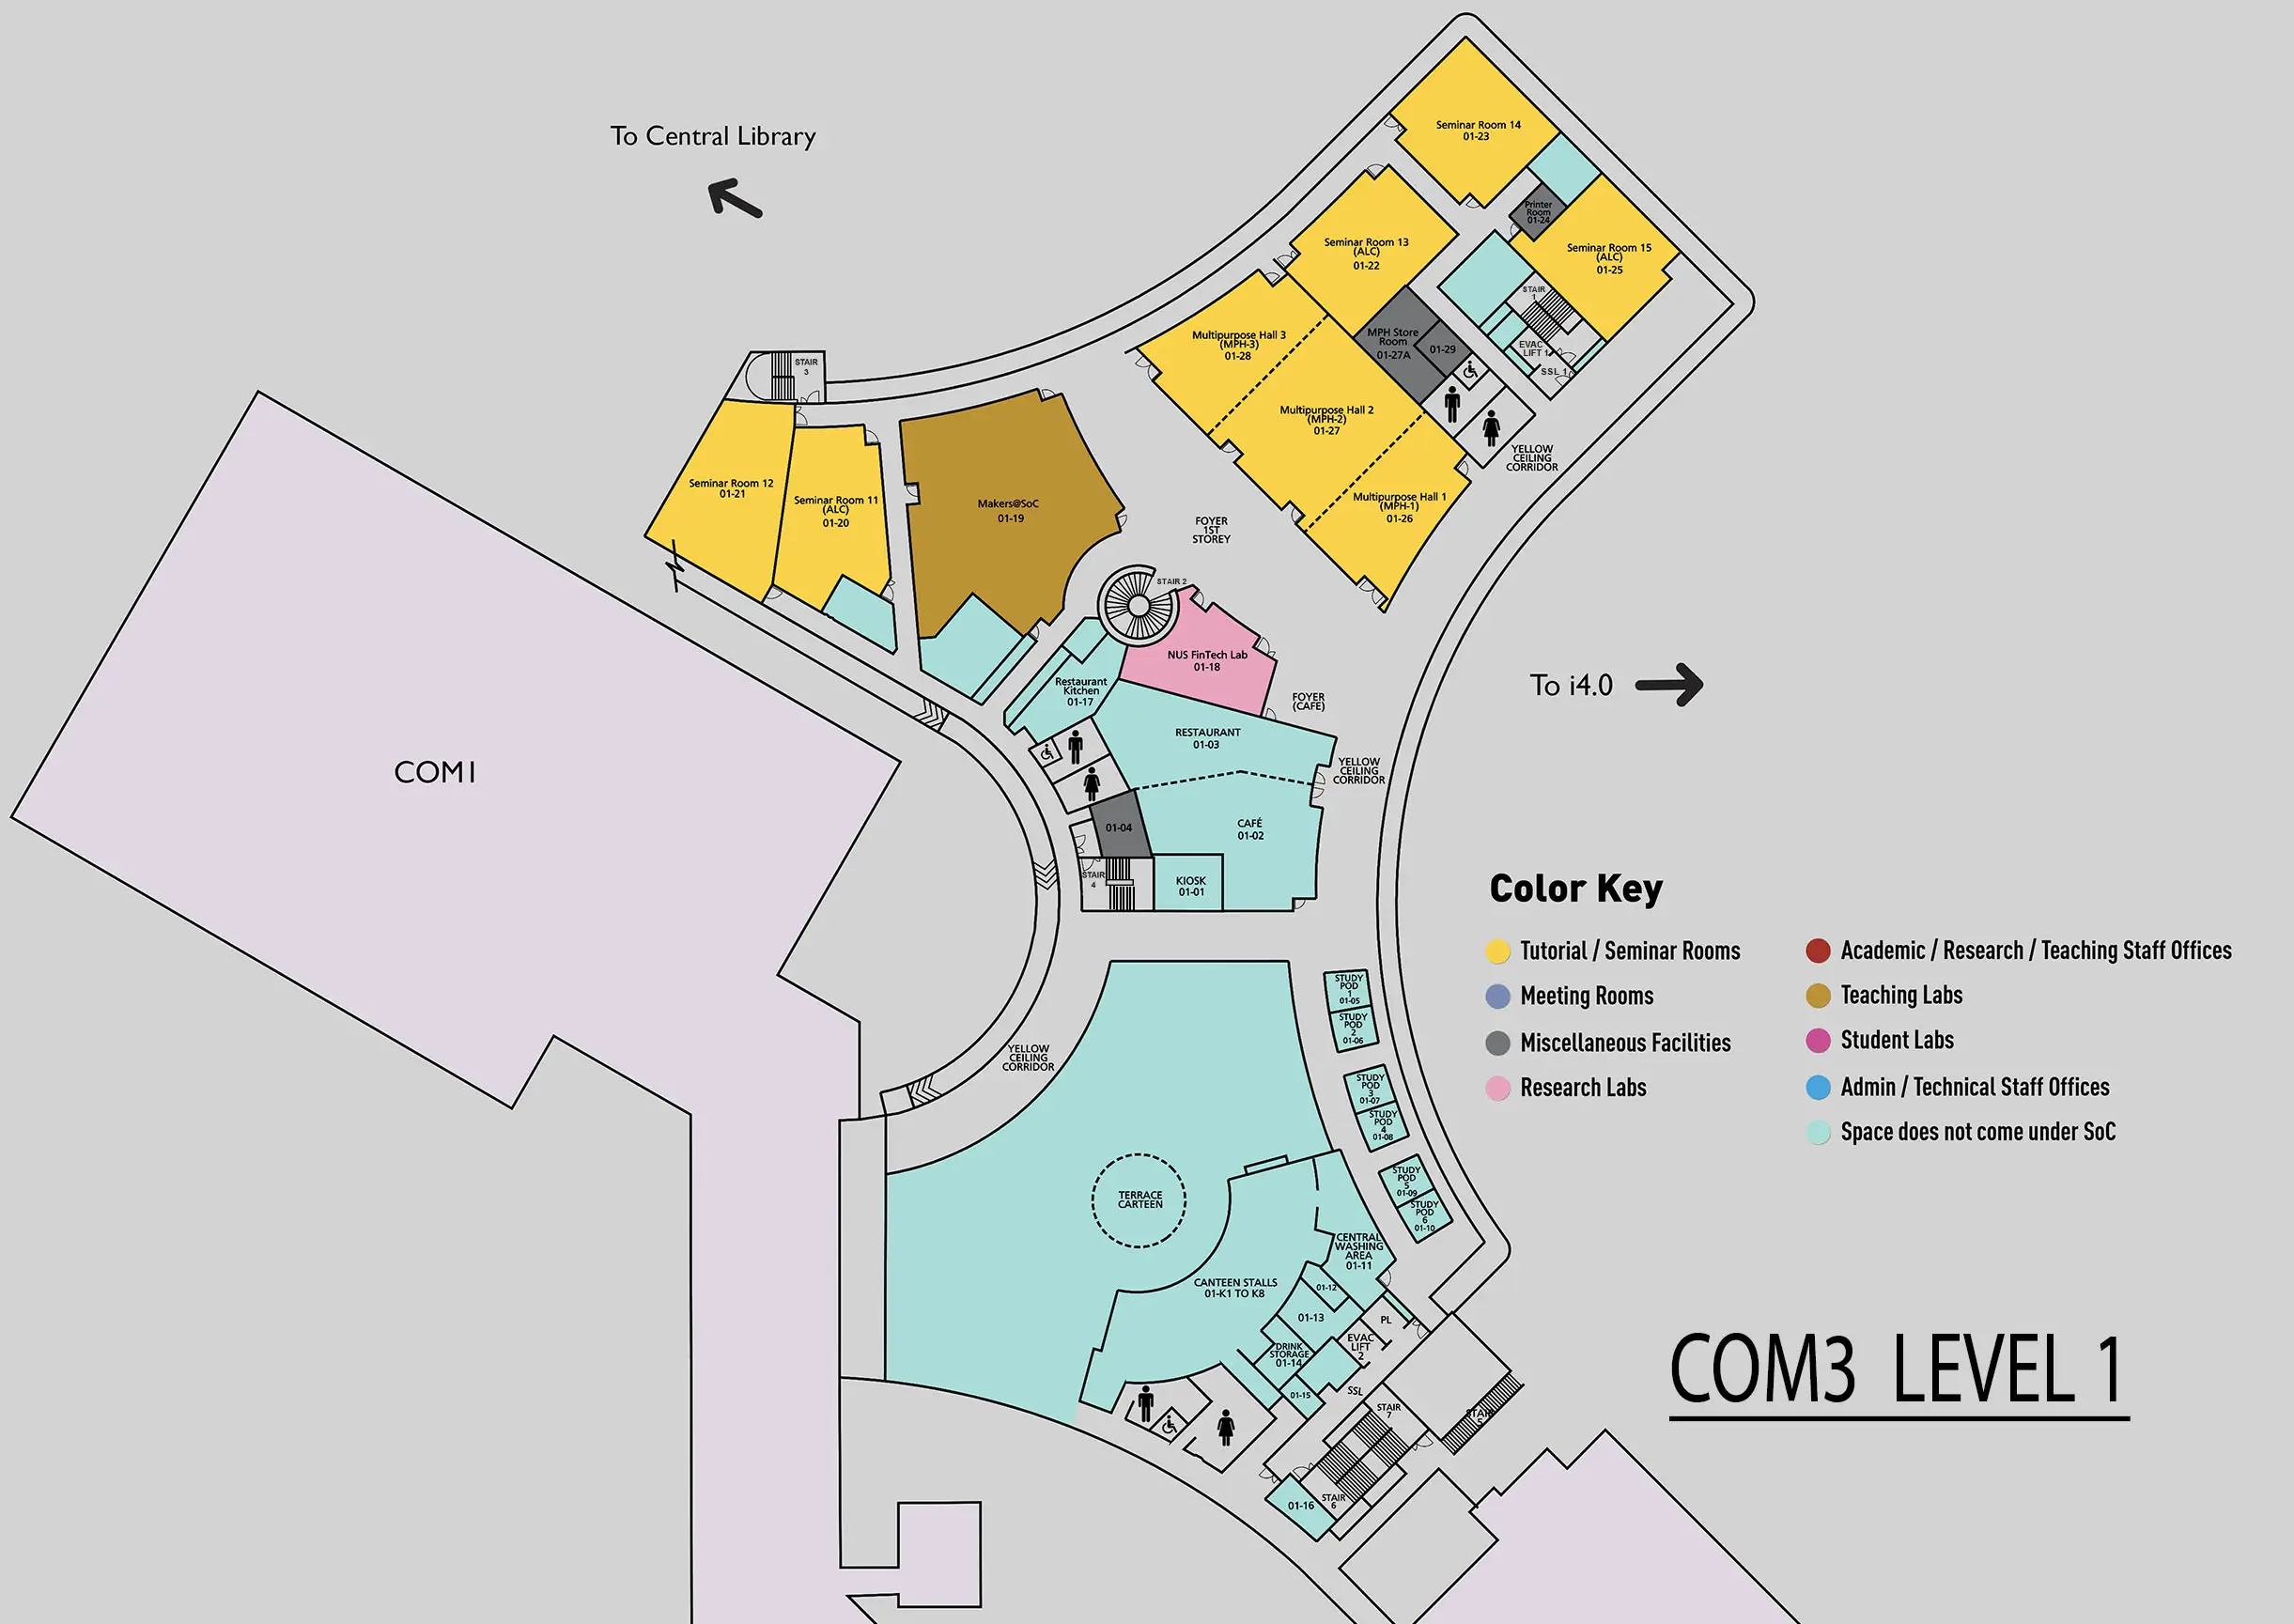
COM3 Level 1
SR12, COM3 01-21
Abstract:
Deep Neural Networks (DNNs) have shown tremendous promise in a variety of applications, but their deployment on resource-limited edge devices presents significant challenges due to their size and computational demands. Existing model compression techniques often fall short by being oblivious to downstream user-specific tasks and applications. This thesis addresses the challenge of adapting DNN models effectively on resource-limited hardware, advocating for flexible and efficient models.
Firstly, we tackle the challenge of on-device adaptation for user-specific models, enabling them to dynamically update based on evolving user preferences and data distributions without requiring full retraining. Given the limited on-chip memory capacity on edge devices, data movement becomes a significant bottleneck, leading to increased energy consumption. To address this, we introduce Chameleon, an energy-efficient continual learning framework. Chameleon exploits the hierarchical memory structure typical of edge devices while providing an FPGA-based analytical framework to inform hardware-specific design choices, optimizing performance while minimizing power consumption. Secondly, generic DNN models can lead to wasteful and inefficient inference for end-user applications. To mitigate this, we propose CRISP, a class-aware pruning framework. CRISP employs a hybrid structured sparsity pattern, combining the strengths of fine-grained and coarse-grained structured sparsity to retain essential weights for user-relevant classes, thereby enhancing model efficiency and relevance. Thirdly, while low-precision integer formats are common for reduced precision arithmetic due to simpler hardware implementation, these formats are inadequate for emerging workloads like transformers because of their limited representation range. To overcome this, we explore minifloats, reduced-precision floating-point formats that significantly reduce the memory footprint of a model while offering greater flexibility due to their dynamic range. We implement a custom FPGA-based multiply-accumulate operator library, demonstrating that as the bit-width of floating-point formats decreases, so does the resource footprint. Finally, models such as Vision Transformers (ViTs) are computationally expensive and struggle with real-time inference on edge devices. To address this, we introduce SMS, a token pruning framework that dynamically determines which tokens to merge and to what extent, thereby optimizing model accuracy while adhering to the target average inference budget for devices like Jetson Nano and RPi. This approach confines token merging to selected layers while pursuing aggressive token reduction.
These techniques, evaluated extensively through experimentation, demonstrate significant improvements in model efficiency and adaptation on edge devices while maintaining or even enhancing performance for specific end tasks.